There will be no AGI without spatial intelligence.
We build spatial AI models and services so people and machines can reason, learn and act safely in the physical world.
World models imagine the world. We measure it: metric scale, geometry, coordinates and georeferencing.
- Turn imagery into ground truthOrdinary imagery is enough for our models to learn a place. No special hardware.
- Measure, don’t imagineGeoreferenced Gaussian splats and an aligned mesh, at metric scale.
- Position with precisionPrecise 6DoF or 3DoF pose in a shared coordinate system, even without GPS.
- Reason about real placesDetect objects and change over time, and question a scene in plain language.
Imagined worlds only need to look plausible. Physical AI needs to know the real one.
AI has learned from the text, images and video online. The physical world is the missing training set. Robots, agents and autonomous systems need to know where things are, what they are and how they change, and they can't learn that from a generated scene.
We start where a simulated world isn't good enough.
Industrials, defense and robotics: the places where safe autonomy matters most. If it works there, it works anywhere.
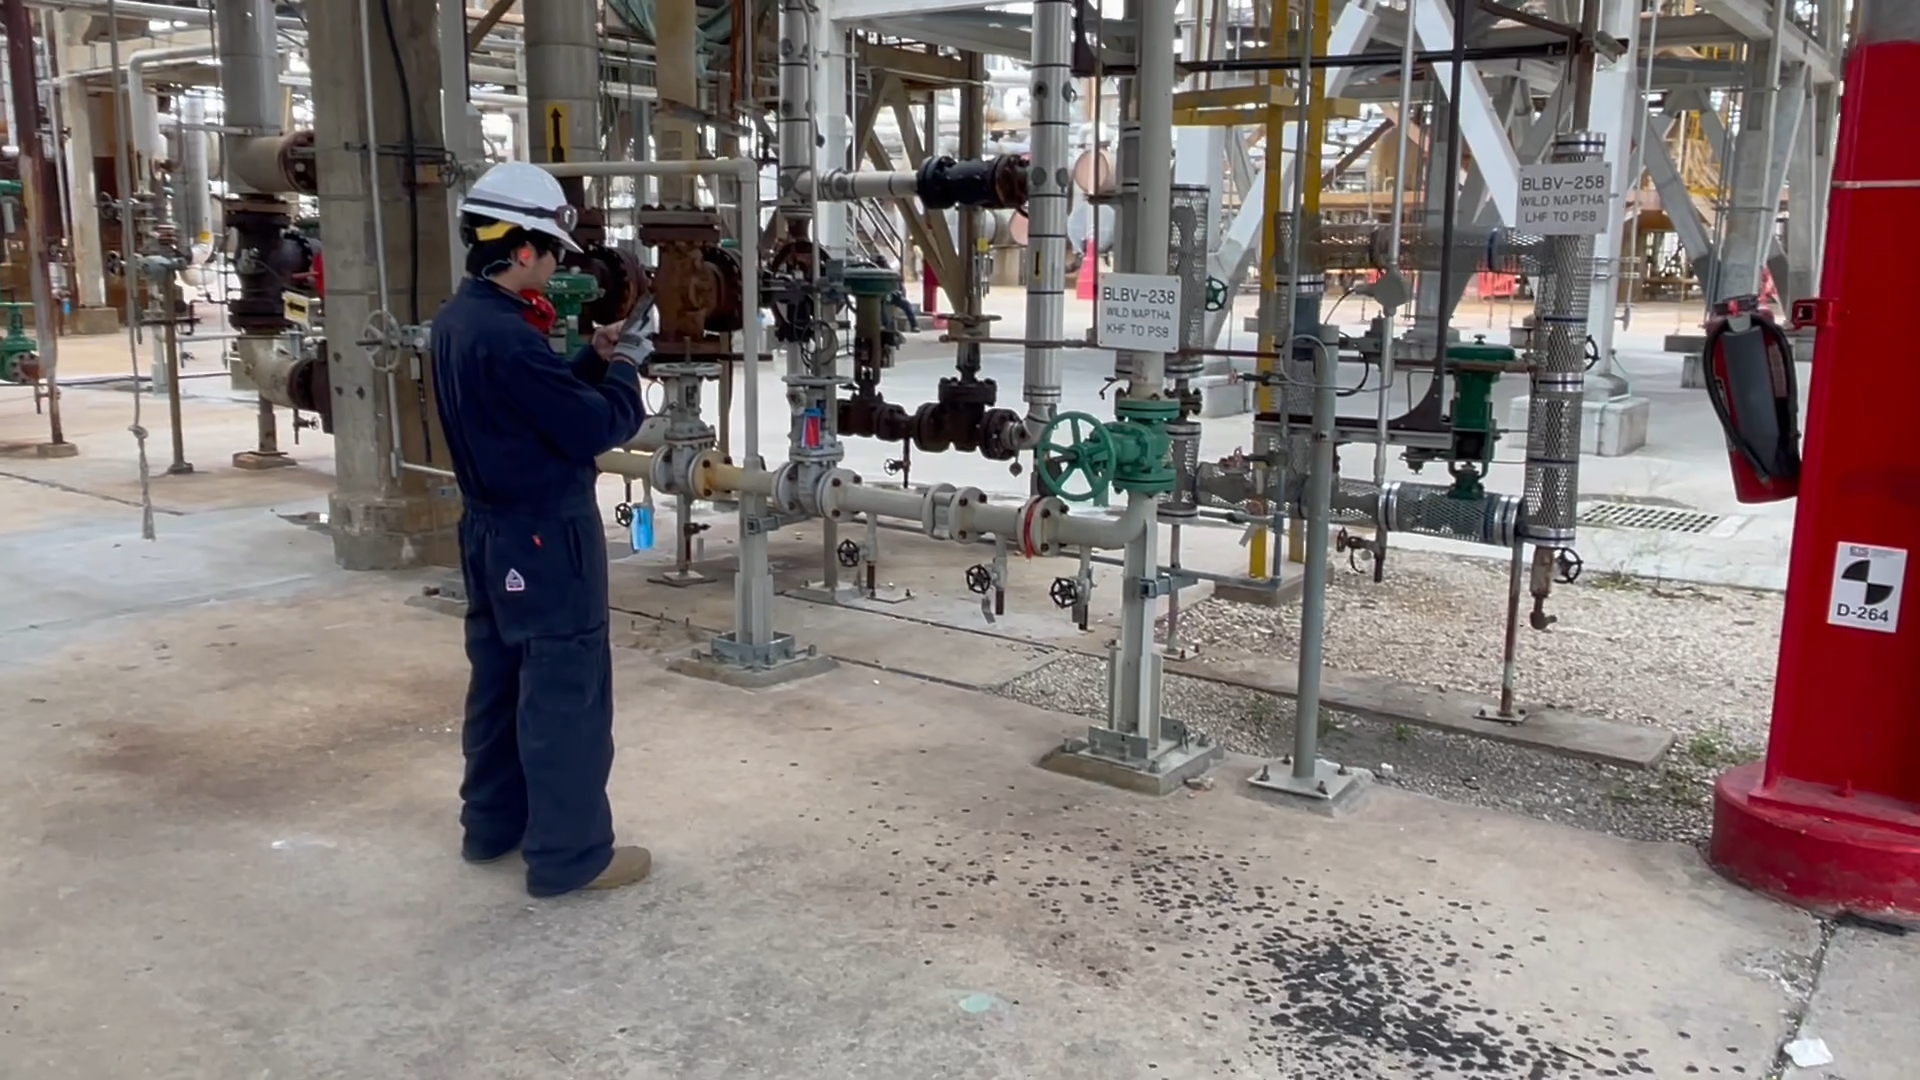 Intelligent field operations, at every facility.Existing capture data becomes a current 3D record that crews and machines can search, inspect and act on.Explore oil and gas
 One shared 3D picture, even where GPS is jammed.Drone, satellite and ground imagery fused into a 3D common operational picture for rehearsal and missions.Explore defense and intelligence
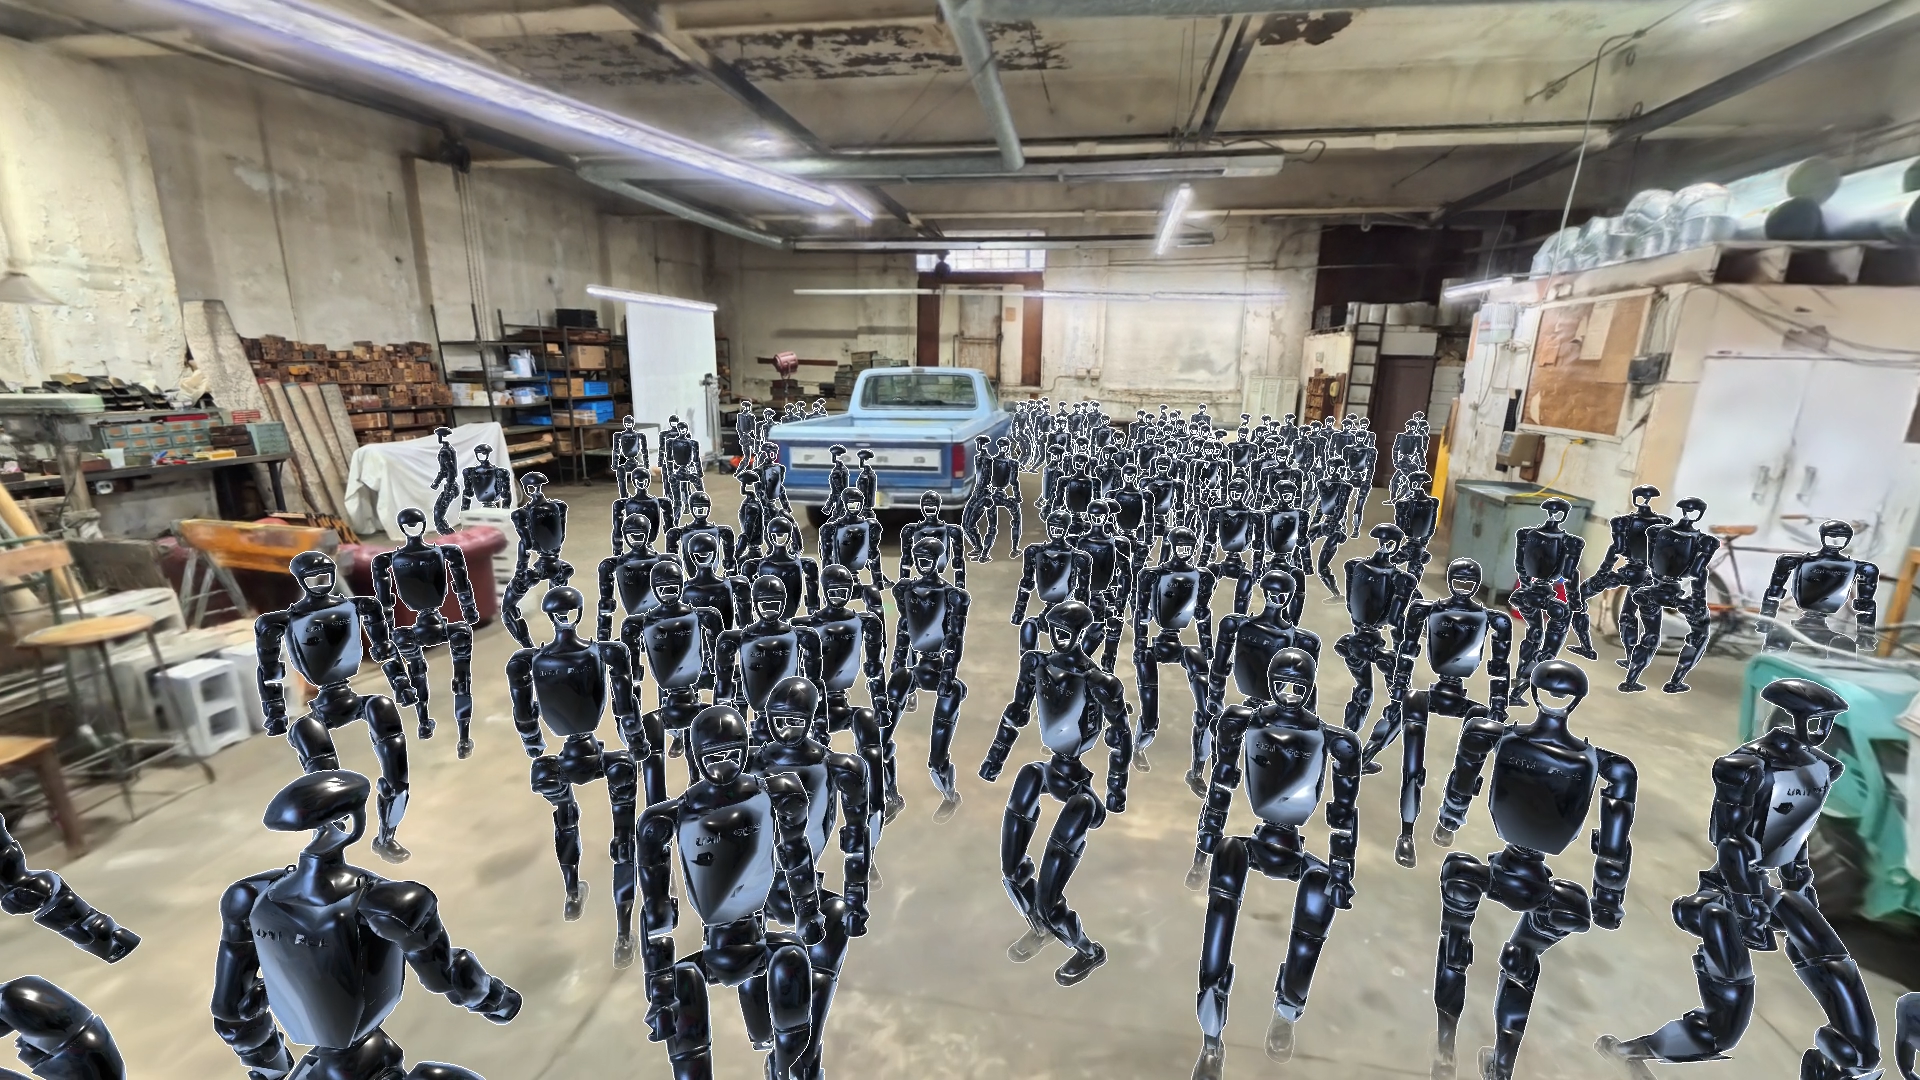 Train robots in the real place they’ll work.A few minutes of camera footage becomes a photoreal, metric-scale, collider-ready environment for simulation.Explore embodied AI
Research that ships.
Our team publishes at CVPR, ICCV, ECCV, NeurIPS and ICLR, and our research feeds the same foundation models our customers run.
All publications MVSAnywhere: metric depth for any scene, zero-shotFrom posed images, one general model predicts sharp, metric-accurate depth across indoor, outdoor and aerial scenes.
 ACE-G: localization in places it has never seenPretrained across tens of thousands of real places, one model localizes in new scenes without retraining.
 Cross-View Splatter: 3D from the street and the skyFuses satellite views with ground photos into Gaussian splats of large outdoor scenes, in one shared frame.
Every place you capture makes the world more legible to machines.
We turn captures from any sensor or archive into a 4D neural map of each place, kept current for people and machines to act within.


